MLOps Observability & Monitoring
You can learn the key ideas behind observability in context of ML
ML systems don’t fail loudly. They degrade quietly – a prediction score that drifts by 3% a week, a batch pipeline that stalls without alerting, a RAG index that goes stale without anyone noticing. By the time users report problems, the damage is done. This course gives you the full observability stack for ML: the signals to collect, the dashboards to build, the alerts to configure, and the on-call playbook to follow when something breaks.
- Instrument online serving and batch pipelines with ML-specific metrics, structured logs, and distributed traces
- Build drift detection jobs and online evaluation feedback loops that act before users notice
- Publish Grafana dashboards covering service health, model quality, data freshness, and SLO error budgets
- Configure multi-stage alerts with routing, deduplication, and runbook links for ML on-call
- Apply observability to LLM/GenAI workloads – quality proxies, RAG freshness, and token cost monitoring
Sound familiar?
Your ML system is running. But you’re not sure it’s working.
Infrastructure monitoring tells you whether your servers are up. It doesn’t tell you whether your model’s predictions are drifting, whether the features feeding it are stale, or whether a silent schema change upstream has been corrupting your outputs for the past two weeks. ML observability is a different discipline, and most MLOps engineers have never had to build it from scratch.
What makes this different
Not infrastructure monitoring applied to ML.
Observability designed for what ML systems actually are.
Standard observability courses teach you to monitor services. ML systems need more: prediction quality signals, data freshness checks, drift detectors, and feedback loops that close the gap between deployment and ground truth. This course teaches the ML observability layer that sits on top of standard infrastructure monitoring — and integrates with it.
ML-specific signal design — the layer infrastructure monitoring misses
The course starts with telemetry design: labelling metrics with model_name, model_version, and dataset_version; propagating request and correlation IDs across ML services; avoiding cardinality traps. These design decisions determine whether your observability data is useful or overwhelming.
SLOs defined at the model layer, not just the service layer
Standard SLOs cover latency and error rate. ML SLOs cover prediction quality proxy, drift rate, and data freshness — metrics that require ML-specific instrumentation. The SLIs/SLOs module teaches you to define, document, and link these to runbooks, so your on-call process is grounded in ML-meaningful thresholds.
Full three-pillar stack: metrics, logs, and distributed traces — all with ML context
Separate modules for instrumenting serving, instrumenting batch pipelines, building structured JSON logs with model references, and adding OpenTelemetry traces with spans across feature retrieval → model → downstream. You build all three pillars, not just dashboards over a single signal type.
Grafana dashboards for four distinct views: service, model, data, and SLO
The dashboards module builds four separate views — service health, model quality and drift, data freshness and completeness, and SLO error budget burn. You publish them with saved views so the right dashboard is in front of the right person during an incident.
LLM/GenAI observability as a dedicated module
LLM observability is genuinely different: quality proxy instead of accuracy, refusal/toxicity rate instead of precision, RAG index freshness instead of data freshness, token count as a cost and quality signal. The LLM module covers all of this with a hands-on lab adding LLM metrics and a RAG freshness tile.
Three post-mortems based on realistic production incidents
The case studies module works through three realistic ML incidents — silent feature break from an upstream schema change, concept drift after a promotional campaign, and an LLM RAG index going stale. For each: the detection story, the diagnosis, and the action. You write a structured post-mortem as the module deliverable.
❌ Infrastructure observability courses
✓ MLOps Observability & Monitoring
Learning outcomes
By the end of this course, you’ll be able to:
Six observability capabilities that give your team real-time visibility into every layer of a production ML system — from service health to model quality to LLM RAG freshness.
What you’ll learn
Course Curriculum
Introduction
+
- Course Introduction
- About Your Instructor
- Course Structure
- Churn API + Batch Scoring + LLM/RAG Endpoint — Running Project
- What This Course Covers (and What It Does Not)
- GitHub Repositories
Observability in ML: Goals, Signals, Scope
+
- Why ML Systems Fail in Production — Data, Model, Service
- Observability vs. Monitoring — Where MLOps Is Different
- Three Pillars for ML — Metrics, Logs, Traces with Model/Data Context
- Golden Signals + ML Signals — Quality, Drift, Freshness
SLIs, SLOs, and SLAs for ML Services
+
- Define SLIs for Model APIs — Latency, Error Rate, Throughput
- Define ML SLIs — Prediction Quality Proxy, Drift Rate, Data Freshness
- Set SLOs with Simple Thresholds and Error Budgets
- Document SLOs and Link to Runbooks
Telemetry Design for ML
+
- Labels/Tags for model_name, model_version, dataset_version
- Request IDs and Correlation IDs Across Services
- PII-Safe Logging and Redaction Basics
- Cardinality Traps and Safe Naming Patterns
Instrumenting Online Model Serving
+
- Add HTTP/Server Metrics — Latency Buckets, Status Codes, Timeouts
- Custom Model Metrics — Request Count, Queue Time, Cold Starts, Cache Hits
- Prediction Metrics — Score Histograms, Class Ratios, Confidence Bands
- Health Checks (Readiness/Liveness) and Dependency Checks
- Instrument a FastAPI/KServe Service with Model/Version Labels — Hands-on Lab
Instrumenting Batch & Streaming Pipelines
+
- Batch Pipeline Metrics — Freshness, Completeness, Success Ratio, Duration
- Streaming — Consumer Lag, Partition Skew, Dead-Letter Queue Counts
- Emit Feature Freshness and Backfill Markers
- Add Pipeline Metrics and a Daily Freshness Report — Hands-on Lab
Data Quality & Drift Monitoring
+
- Types of Drift — Covariate, Prior, Concept
- Simple Detectors — PSI, KS Test, Population Shift Checks
- Seasonality and Baseline Windows — How to Avoid False Alarms
- From Detection to Action — Silence, Retrain, Rollback
- Build a Drift Job that Writes Alerts + a Weekly Drift Report — Hands-on Lab
Online Evaluation & Feedback Loops
+
- Capture Ground Truth Safely — Delayed Labels, Queues
- Rolling Metrics — AUC/PR, Calibration on Recent Windows
- Champion/Challenger Tracking in Production
- Log Predictions + Labels and Publish a Weekly Eval Card — Hands-on Lab
Tracing ML Requests End-to-End
+
- Traces and Spans — Feature Retrieval → Model → Downstream
- Propagate Context IDs Across Calls
- Sampling Strategies that Keep Cost Low
- Add OpenTelemetry Traces and View a Request Waterfall — Hands-on Lab
Logging for ML Systems
+
- JSON Logs with model_version, dataset_ref, request_id
- Log Levels and Rate Limiting
- Redaction and Safe Error Details
- Ship Structured Logs and Build a Quick Search View — Hands-on Lab
Dashboards that Drive Action
+
- Service Dashboard — Latency, Error Rate, Throughput
- Model Dashboard — Quality Proxies, Drift Tiles, Version Adoption
- Data Dashboard — Freshness, Completeness, Schema Change Rate
- SLO Dashboard + Error Budget Burn
- Publish Three Grafana Dashboards with Saved Views — Hands-on Lab
Alerts & On-Call for ML
+
- Multi-Stage Alerts — Page on SLO Breach, Ticket on Warnings
- Deduplication and Routing — Teams, Schedules
- Alert Hygiene — Test Alerts, Avoid Flapping, Add Runbook Links
- Configure Alerts for Latency Spike, Drift Spike, Stale Data — Hands-on Lab
Performance & Capacity
+
- Track p95/p99 Latency by model_version
- GPU Utilization, Memory, and Model Load Times
- Simple Capacity Planning Using Recent Traffic and Headroom
- Record a Load Test and Tune Batch Size/Concurrency — Hands-on Lab
Cost-Aware Observability
+
- Approximate Cost per Prediction and Cost per Batch
- Emit Cost Hints — GPU Hours, Storage Reads — to Metrics
Security Signals
+
- Access Logs, Auth Failures, Request Anomalies
- Model Abuse Patterns — Prompt Abuse for LLMs, Request Floods
LLM & GenAI Observability
+
- LLM SLIs — Latency, Quality Proxy, Refusal/Toxicity Rate, Token Counts
- RAG Freshness — Index Age, Chunk Coverage, Hit Ratio
- Offline Eval Sets vs. Online Probes — Feedback Collection
- Add LLM Metrics + a RAG Freshness Tile to Grafana — Hands-on Lab
Case Studies & Post-Mortems
+
- Schema Change Upstream — Silent Feature Break → Detection → Rollback
- Concept Drift After Promo — Quality Drop → Challenger Promoted
- LLM RAG Staleness — Index Not Refreshed → Fix with Scheduled Rebuild
- Write a Short Post-Mortem and Action Items
Is this course right for you?
Built for engineers who need to know what their ML systems are doing in production — right now
You don’t need to be a data scientist. You need to be the person who knows whether the model is working, why it might not be, and what to do about it at 2am when the page fires.
Prerequisites — what you need before starting:
✓ You need
✗ You do NOT need
MLOps Specialization path
This is Course #1 of the full
MLOps Specialization
Each course builds on the previous one. Start here to get your field overview – then go as deep as your career requires.
Start with MLOps Fundamentals and decide your next step based on your career goals.
Start with Course #1 – Enroll NowComing soon
Be first when MLOps Observability & Monitoring launches
Join the waitlist to secure subscriber pricing and get notified the moment the course goes live. Everything planned, confirmed from the curriculum draft:
-
16 content modules — full observability stack From SLO definition and telemetry design through dashboards, alerts, LLM observability, and post-mortems.
-
10 hands-on labs — one per instrumentation topic Instrument FastAPI/KServe, build drift jobs, add OpenTelemetry traces, publish Grafana dashboards, configure ML alerts.
-
3 post-mortems — realistic ML production incidents Schema break, concept drift, and LLM RAG staleness — write a structured post-mortem for each.
-
Certificate of Completion Step 7 of the MLOps Specialization credential path.
- ✓ 16 content modules confirmed
- ✓ 10 hands-on labs
- ✓ 3 post-mortems
- ✓ Capstone + instructor review
- ✓ Certificate of Completion
Course credential
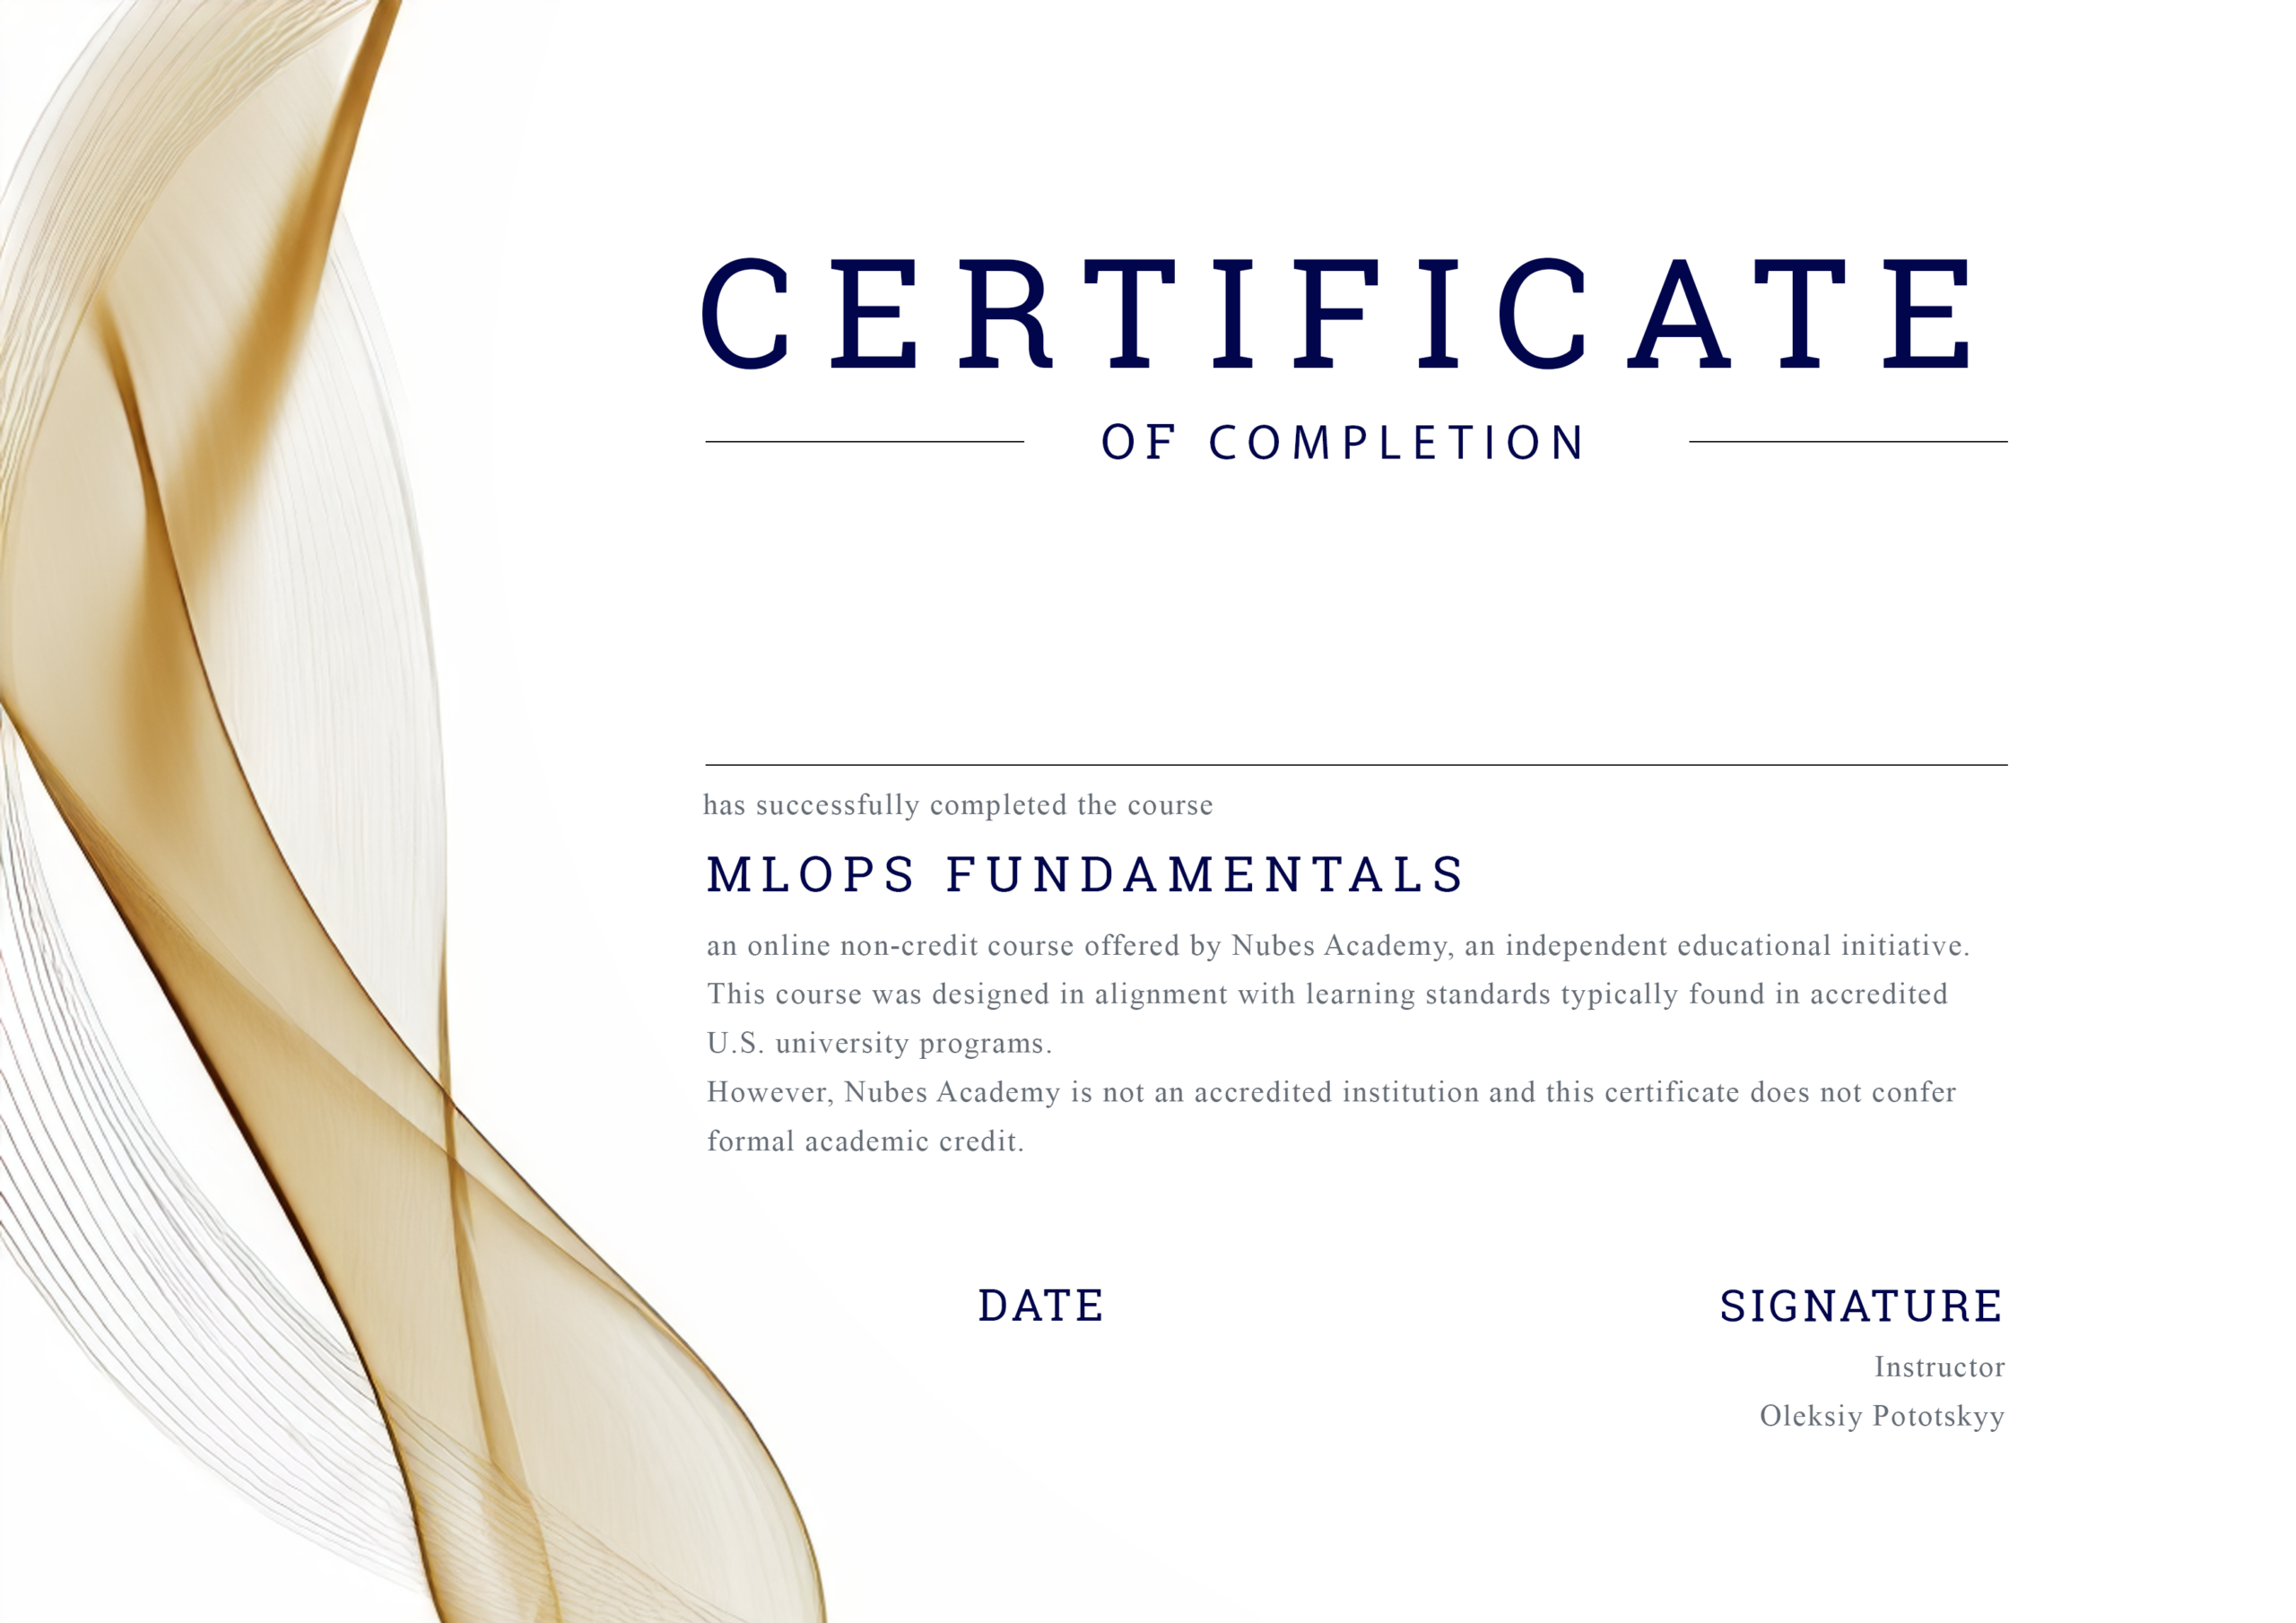
Certificate of Completion
Complete the course and earn a Certificate of Completion in MLOps Observability & Monitoring — shareable directly to your LinkedIn profile and CV. Production ML observability — covering model quality monitoring, drift detection, and LLM-specific signals — is one of the most in-demand senior MLOps skills and a credible differentiator in technical hiring.
This certificate is Step 7 of the MLOps Specialization. Nubes Academy is developing university accreditation partnerships for the full specialization — the credentials you build today are designed to grow into something recognized beyond a standard online course certificate.
Your instructor
About Your Instructor
Alex is an Independent Consultant with 20+ years of experience across Software development, DevOps, Architecture, and technical leadership. He developed and delivered Cloud & DevOps curriculum at Master’s Degree level at a university, and continues to work as an active practitioner alongside building Nubes Academy.
What makes Alex’s approach different: his courses are built from data, not assumptions. The MLOps Fundamentals curriculum was designed by analysing what MLOps engineers actually do in production, not by following a generic textbook outline. The result is a course that covers what your future employer expects, explained in a way that makes sense if you already think like an engineer.
If you have a background in IT, and you want to understand where ML fits into the systems you already work with – this course was built for exactly where you are.
Got questions?
Frequently asked questions
Still have questions? Email us directly — we reply within 1–2 business days.
It’s not just skills. It’s your next chapter.
Stay ahead
New courses.
Better price.
Subscribers first.
- Subscriber-only discount on every new course in the MLOps Specialization – before public launch price applies
- Early access to new courses when they go live.
- MLOps job market insights – what skills employers are actually hiring for, based on real job description data
- Practical guides & free content – no noise, only what matters for engineers moving into MLOps
Get early access & subscriber discounts No spam. Unsubscribe any time.
Your data is stored securely and never shared with third parties. · Privacy Policy